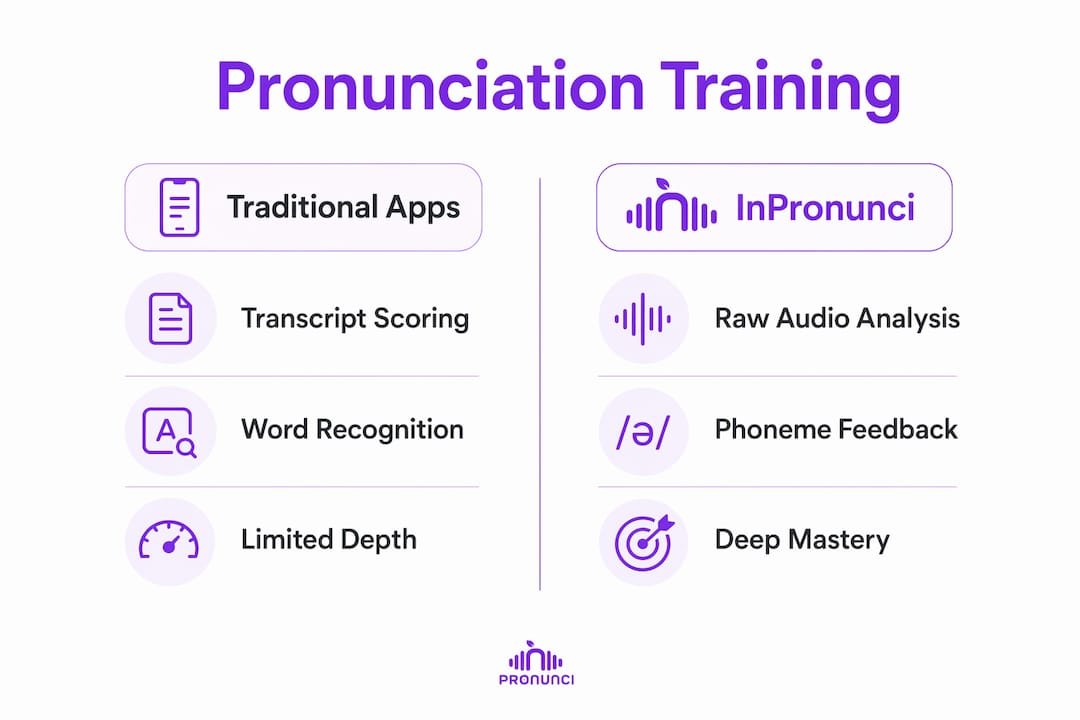
Most mainstream ESL apps fail at deep pronunciation training for one core reason: they route your audio through a speech-to-text engine, convert it to a text transcript, and then score that transcript. The acoustic detail that defines real phonetic accuracy, vowel quality, voice onset time, pitch contour, and stress timing, never reaches the feedback model. The result is a system that can tell you what you said but cannot tell you how you said it.
Here is what that failure looks like in practice:
- STT transcription bottleneck. Your audio becomes text before any analysis happens. Subtle mispronunciations that produce the right word are invisible to the system.
- Coarse phoneme scoring. Most apps score at the word or sentence level, not at the individual sound level. A vowel that is 40% off target still earns a green checkmark if the word is recognized.
- No suprasegmental feedback. Stress, rhythm, and intonation patterns are rarely measured. Apps that do attempt it typically flag only extreme deviations.
- Weak motor learning design. Pronunciation is a physical skill. Apps built around short gamified sessions and “repeat-after-me” drills do not structure practice for articulatory motor retention.
What you should do right now:Look for tools that analyze raw audio acoustics, provide phoneme-level scoring with reference audio, and include speech-organ articulation training. Start with Inpronunci’s free Chapter 1, “Get to Know Your Speech Organs,” to test what phonetics-first feedback actually feels like before committing to any plan.
Pro Tip: Before downloading any pronunciation app, ask one question: “Does it analyze my raw audio, or does it convert my speech to text first?” That single answer tells you whether the feedback can ever reach phonetic depth.
Why mainstream ESL apps miss pronunciation depth by design
Understanding the failure requires looking at how these apps are built, not just what they teach. The dominant architecture in mass-market language apps follows a predictable pipeline: your voice is captured, passed through a speech-to-text engine, converted to a text string, and then evaluated by a rule-based or AI language model that compares your transcript to the expected answer. Pronunciation feedback built on this pipeline loses every acoustic feature the moment audio becomes text.
Business constraints reinforce this design. Freemium and ad-supported models require low compute costs per user, which makes acoustic-native audio processing, the kind that measures F1/F2 formants, voice onset time, and pitch contour directly from the waveform, economically difficult to scale. Apps also compete on engagement metrics: daily streaks, XP points, and short sessions that feel rewarding. Deep phonetic correction is slow, effortful, and sometimes discouraging. It does not fit a gamified UX designed to keep users opening the app every morning.
The result is a set of common UX patterns that feel productive but produce shallow learning:
- Repeat-after-me drills scored by word recognition, not phonetic accuracy
- Sentence-level “correct/incorrect” feedback with no breakdown by sound
- Gamified streaks that reward consistency but not quality of production
- Limited speaking-only lesson design, with most practice time spent on reading, translation, or multiple-choice tasks
Teacher surveys and classroom case studies consistently confirm that mass-market apps work reasonably well for vocabulary and low-level grammar but fall short for speaking practice and higher-level pronunciation instruction. That gap is not accidental. It is the product of deliberate design priorities.
The specific pronunciation dimensions apps consistently miss
The shortcomings are not vague. Each one maps to a concrete linguistic feature that advanced learners need and that text-based feedback cannot reach.
Segmental features
- Vowel quality (F1/F2 formants). English vowel distinctions like /ɪ/ vs. /iː/ (“ship” vs. “sheep”) depend on precise tongue height and backness. STT systems recognize the intended word even when the vowel is produced incorrectly, so the error goes unreported.
- Voice onset time (VOT). The timing gap between a stop release and the start of voicing distinguishes /p/ from /b/ and /t/ from /d/ in English. This is a millisecond-level acoustic event that a text transcript cannot capture.
- Allophony. The /t/ in “butter” is a flap in American English, not a stop. Apps that score at the word level never teach these context-dependent sound variants.
Suprasegmental features
- Lexical stress. Misplaced stress changes meaning (“REcord” vs. “reCORD”) and signals non-native accent even when every phoneme is correct.
- Sentence rhythm. American English is stress-timed. Non-native speakers often produce syllable-timed rhythm, which sounds unnatural even when individual words are accurate.
- Intonation contours. Rising vs. falling pitch at sentence boundaries signals questions, statements, and speaker intent. Coarse scoring does not correct these patterns.
Connected speech
Isolated-word drills do not generalize to real conversation. Reduction (“gonna,” “wanna”), linking (“an apple” sounds like “anapple”), and assimilation (“did you” becomes “didja”) are features of fluent American speech that only appear in continuous utterance practice.
Motor learning structure
Pronunciation is a motor skill. Research on feedback timing and motor adaptation shows that brief, high-frequency attempts with immediate micro-feedback and variable practice contexts produce better retention than massed repetition of isolated tokens. Most apps invert this: they offer long sessions of the same drill type with delayed or absent corrective feedback.
Pro Tip: For motor retention, practice one target sound in at least three different word contexts per session, for example /æ/ in “cat,” “have,” and “actually.” Variable context forces your articulators to generalize the movement, not just memorize one position.
Here is a ranked view of what advanced learners need most, from most to least commonly missed by apps:
- Real-time phoneme-level acoustic feedback
- Suprasegmental correction (stress, rhythm, intonation)
- Connected speech and fluency drills
- Articulation training (tongue, lip, jaw position)
- Motor-learning-aligned practice sequencing
Why these gaps hurt advanced learners and classroom instruction most
For a beginner, an app that confirms word recognition is genuinely useful. For an advanced learner, that same confirmation becomes a liability. You practice confidently, the app says you are correct, and your error pattern fossilizes. Research on phonological transfer shows that persistent error patterns become harder to correct the longer they go unaddressed, a process called phonological fossilization.
The plateau effect is real and specific. Advanced learners who rely on app feedback often develop a false sense of mastery because their speech is intelligible enough for STT recognition but still carries suprasegmental patterns that signal non-native accent to human listeners. Professional clarity, the kind needed in job interviews, client meetings, and academic presentations, requires suprasegmental accuracy that text-based feedback simply cannot assess.
For educators, the classroom consequences are concrete. Teachers using apps as primary speaking tools frequently need to add supplemental activities to fill the gaps. A qualitative case study of app-based instruction found that many educators incorporated role-play, group discussion, and targeted pronunciation drills specifically to compensate for what the app could not address.
Teacher diagnostic checklist: When a student says “the app says I’m correct,” ask these questions:
- Can you produce that sound in three different word positions (initial, medial, final)?
- Does your stress pattern match the native model when you say the full sentence?
- Record yourself and compare to a native speaker at the sentence level. Does the rhythm match?
- Can you produce the target sound in spontaneous speech, not just in the drill?
A practical classroom adaptation: use app-based drills for individual sound exposure, then follow with a 5-minute paired speaking task where students use those sounds in unrehearsed sentences. The teacher listens for suprasegmental accuracy, not just word-level correctness. Cross-linguistic instruction strategies, including those used in bilingual and multilingual classroom contexts, confirm that explicit phonological contrast training accelerates this kind of correction.
Research-backed technologies that actually produce pronunciation depth
The technical solution to the STT bottleneck is audio-native processing: analyzing the raw waveform directly rather than converting speech to text first. Acoustic-native pipelines can measure the features that matter for phonetic accuracy, including F1/F2 formant values for vowel quality, voice onset time for stop consonants, duration ratios for vowel length distinctions, and pitch contour for intonation.
When systems invest in this level of analysis, the results are measurable. A recent study found that detailed AI pronunciation feedback produced a measurable phonetic accuracy improvement compared to control conditions. Systems capable of this analysis are more expensive to run, which is why they remain rare in freemium products.
| Feedback Type | What It Measures | Typical Accuracy Gain |
|---|---|---|
| STT transcript scoring | Word recognition only | Minimal for phonetics |
| Phoneme-level acoustic analysis | Vowel quality, VOT, duration | About 15 percentage points (2025 study) |
| Suprasegmental feature extraction | Pitch contour, stress, rhythm | Measurable prosody correction |
Articulation training adds a second layer. Showing jaw, tongue, and lip movement alongside a live acoustic target helps learners link physical sensation to acoustic output faster than audio-only feedback. This is the principle behind
InPronunci training structure
How InPronunci trains the American speech system
InPronunci trains the full American speech system: Interactive Visual 2D Sound Simulators and phonetic exercises for articulation and American sound development, sentence practice for intonation, melody, rhythm, and connected speech, paragraph practice for spontaneous speech, public speaking, and real communication confidence, and Advanced AI Accent Coach evaluation as you speak.
InPronunci is an advanced, linguistically structured American accent training platform with more than 1,000 downloads and a growing learner base. It is designed for serious ESL learners who want American pronunciation, stronger intonation, more natural rhythm, better connected speech, and the ability to speak English more confidently in real communication. The program is especially useful for intermediate and advanced English speakers who want to become independent speakers of English with confident communication, stronger speaking control, long-term speech improvement, and great public speaking skills. It is also designed for advanced speakers whose goal is to speak like a native or closer to native-like American speech, including people who were raised in the United States but still have slight accent patterns from the native language they were born with. It is a complete American accent training course and system created by Prof. Alex, Ph.D. Accent Coach, Doctor of Education, and professional linguist based in Austin, Texas, with Pronunci Instructions from Prof. Alex for each lesson that make self-learning more effective, supported, and clear.
: learners see the movement, attempt it, and receive acoustic confirmation in the same session.
The best training protocols combine these elements in sequence:
- Articulation training to establish the target movement
- Immediate acoustic feedback on the learner’s attempt
- Variable practice across multiple phonetic contexts
- Spaced repetition across sessions to consolidate motor memory
- Human coaching checkpoints to catch errors the system cannot flag
What to look for in an app when you need deep pronunciation training
Not every app that claims “AI pronunciation feedback” delivers acoustic-native analysis. Here is a checklist you can use to evaluate any tool or program before committing time to it.
Core criteria:
- Analyzes raw audio acoustics, not STT transcripts
- Provides phoneme-level scoring with a native reference audio comparison
- Gives feedback on stress, rhythm, and intonation, not just individual sounds
- Includes articulation training (tongue, lip, jaw position)
- Offers real-time corrective feedback during practice, not only post-session summaries
- Structures practice for motor learning (short, frequent, variable drills)
- Provides a human coaching path for personalized correction
Questions to ask any provider:
- Do you analyze raw audio acoustics or only STT transcripts?
- Can you show me phoneme-level metrics with reference audio?
- How is feedback timed? Is it immediate or delayed?
- Does your practice design vary phonetic context across drills?
- Is there a human coach available for errors the AI cannot catch?
A 10-minute trial protocol for educators evaluating tools:
- Record yourself producing a target sound in three word contexts.
- Download or screenshot the feedback report.
- Compare the app’s feedback to a native reference recording.
- Check whether the feedback identifies the specific acoustic error or only marks the word correct/incorrect.
- Have a colleague or coach verify whether the feedback matches what they hear.
For a structured comparison of AI accent coaching options, the AI Accent Coach guide walks through these evaluation criteria in detail.
How Inpronunci addresses each gap: features, evidence, and student outcomes
Inpronunci was designed by Prof. Alex, Ph.D., a linguist who trains translators and interpreters, specifically to address the structural failures described above. The course is built for intermediate and advanced learners, not beginners, and every feature maps directly to a gap that mass-market apps leave open.
| App Shortcoming | Inpronunci Feature That Addresses It |
|---|---|
| STT bottleneck, no acoustic analysis | AI Accent Coach analyzes pronunciation, intonation, rhythm, and connected speech from your actual speech |
| No articulatory guidance | 2D Sound Video Mouth-Training Simulators train tongue, lip, jaw, and airflow movement for every American sound |
| No suprasegmental feedback | Dedicated practice and evaluation modes for stress, rhythm, intonation, and connected speech |
| Weak motor learning design | Human-guided instructions structure practice like a real coaching session, with sequenced drills and feedback loops |
| No human correction path | Premium Plan includes 1-on-1 monthly sessions with Prof. Alex, Ph.D. |
Three learners, Andrew, Thiago, and Tian, documented their progress through Inpronunci’s structured curriculum. Their before-and-after recordings, available at Andrew’s progress video, Thiago’s progress video, and Tian’s progress video, show measurable shifts in vowel quality, stress placement, and connected speech fluency across a structured training period.
Structured American Accent Training Course
From Speech Organs Education to American Intonation
The InPronunci course is built step by step: every chapter prepares the next one, and by the end of the course students receive a certificate.
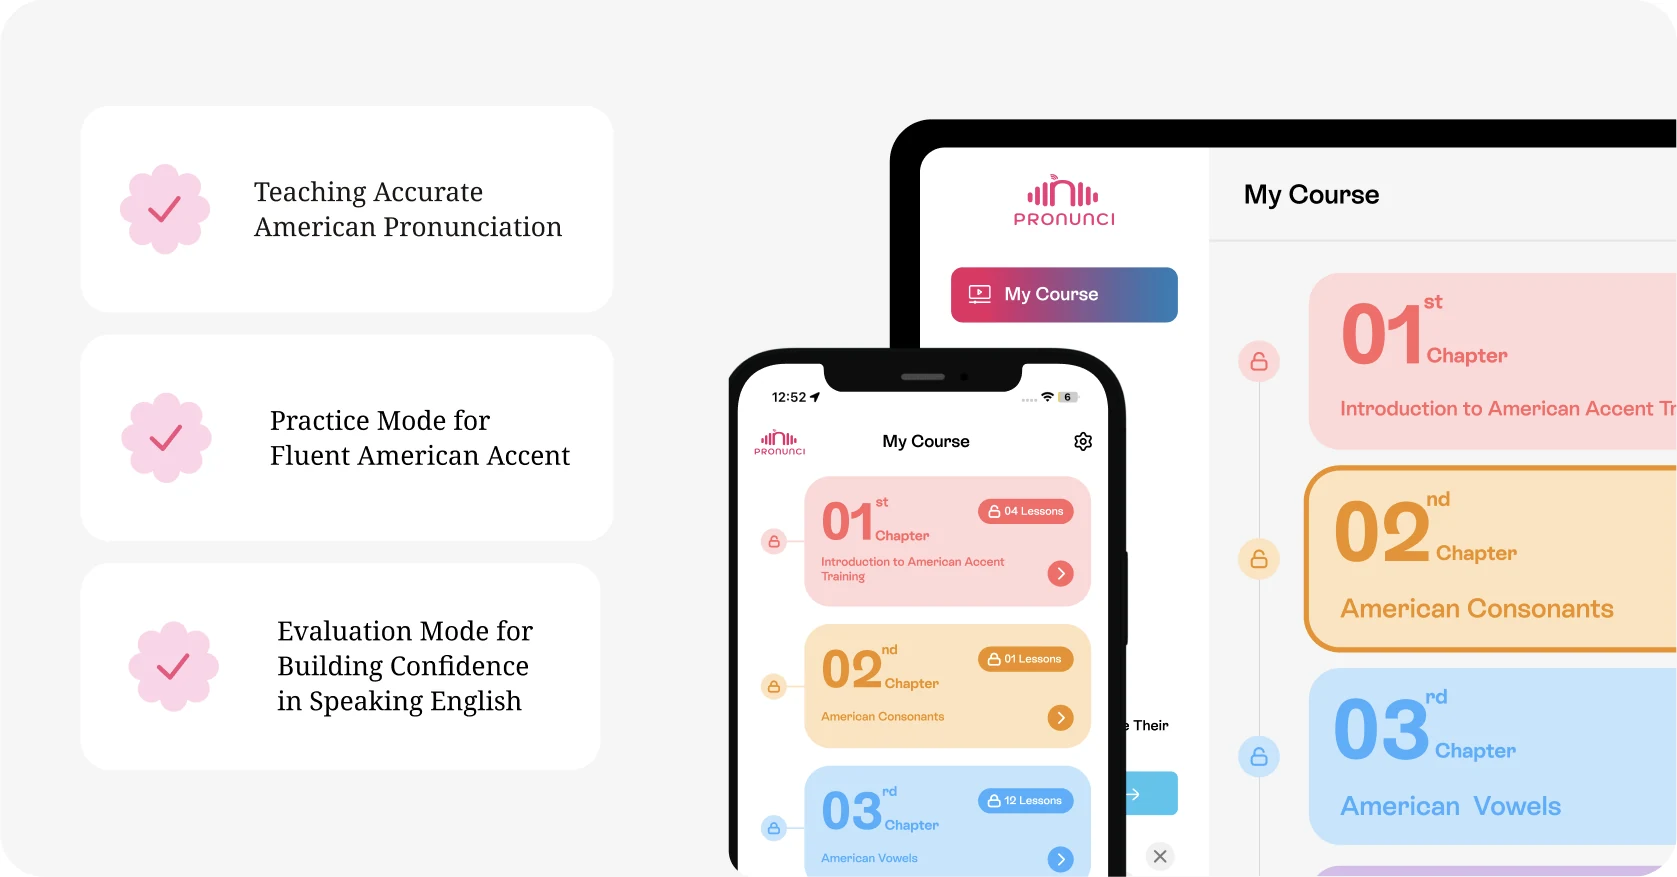
- Speech Organs EducationStudents learn how the speech organs work, along with the AI Accent Coach commands and feedback.
- American ConsonantsPractice and evaluate American consonants in phonetic exercises and practice sentences with the AI Accent Coach.
- American VowelsPractice and evaluate American vowels in phonetic exercises and practice sentences with the AI Accent Coach.
- IntonationLearn how intonation can change the meaning of what you say.
- CertificateBy the end of the course, students receive a certificate.
Pro Tip: Start with the free Chapter 1, “Get to Know Your Speech Organs.” It builds the physical awareness you need to interpret every piece of feedback that follows. Learners who skip this step often misread their own errors.
Inpronunci offers three entry points: the free Chapter 1 for onboarding, the Basic Plan for self-study guided by the AI Accent Coach and human-guided instructions, and the Premium Plan for learners who want 1-on-1 monthly sessions with Prof. Alex, Ph.D. For educators, the structured training vs. apps comparison explains how to integrate the platform alongside classroom instruction.
A practical training plan for advanced learners and educators
Measurable suprasegmental improvement typically appears within 6–12 weeks of structured, daily practice. The timeline depends on how consistently you practice and whether you have corrective feedback at the phoneme level.
Weekly micro-session plan (20–30 minutes per day):
- Days 1–2: Articulatory focus. Work through one target sound using a 2D simulator. Practice in three word contexts. Record and compare to native audio.
- Days 3–4: Sentence-level stress and rhythm. Take two sentences from real speaking contexts (a meeting, a presentation). Mark stress patterns. Record, listen, and adjust.
- Days 5–6: Connected speech. Practice one linking or reduction pattern in five different sentence frames. Focus on fluency, not perfection.
- Day 7: Full-utterance review. Record a 60-second spontaneous response on a familiar topic. Evaluate for stress, rhythm, and target sounds. Note two specific items to address next week.
Timeline for measurable gains:
- Weeks 1–3: Increased awareness of your own errors; segmental targets begin to stabilize.
- Weeks 4–6: Stress and rhythm patterns become more consistent in prepared speech.
- Weeks 7–12: Connected speech and suprasegmental accuracy carry over into spontaneous conversation.
For daily practice structure and rationale, short, frequent sessions outperform long, infrequent ones for motor retention.
For educators integrating this into a semester: Assign one phonetic target per week, use app-based drills for individual practice outside class, and dedicate 10 minutes of class time to paired speaking tasks that require the target feature in unrehearsed speech. Human feedback at the suprasegmental level remains the teacher’s most valuable contribution.
The Basic Plan suits learners maintaining steady practice between coaching sessions. The Premium Plan, with monthly 1-on-1 sessions, is the right choice when professional clarity is the goal and you need a trained linguist to identify the errors your own ear cannot catch.
Traditional ESL apps miss pronunciation depth because they score text transcripts, not acoustic features, leaving vowel quality, voice onset time, stress, rhythm, and connected speech entirely outside the feedback loop.
The phonetics-first approach is the only one that works at the advanced level
The conventional wisdom in language-learning technology is that more AI means better pronunciation feedback. That framing is wrong in one important way: the quality of the AI matters far less than what the AI is analyzing. A highly sophisticated language model scoring a text transcript will never catch a vowel that is 30% off target if the word was recognized correctly. The bottleneck is architectural, not algorithmic.
Advanced learners and educators deserve to know this clearly. When a student plateaus despite consistent app use, the problem is almost never effort. It is that the tool they are using cannot see the errors they are making. Suprasegmental patterns, the stress, rhythm, and intonation that native listeners use to judge fluency and professionalism, are invisible to systems that never analyze the audio waveform.
The practical implication for instructors is direct: apps should be used as supplements for individual sound exposure and vocabulary-linked pronunciation, not as the primary vehicle for advanced speaking development. The teacher’s ear, or a system that genuinely analyzes acoustics, must remain at the center of pronunciation correction at the advanced level. Piloting this in a small class is straightforward: run one week of app-only practice, then one week of app plus teacher-led suprasegmental feedback, and compare student self-assessment accuracy. The difference is usually immediate.
If you are an advanced learner ready to test a phonetics-first approach, skip to the Inpronunci free chapter and run the diagnostic yourself.
Inpronunci gives you the depth that mass-market apps cannot
The gap between what most apps promise and what advanced learners actually need is not small. Inpronunci was built to close it. The American Accent Training Course covers every layer that text-based feedback misses: individual American sounds trained through Interactive Visual 2D Sound Simulators, stress and rhythm corrected through dedicated practice modes, and connected speech built through fluency exercises, all with an AI Accent Coach giving you real-time feedback as you speak.
You are not alone with the technology. Human-guided instructions walk you through every exercise the way a real coach would, and Premium members get monthly 1-on-1 sessions with Prof. Alex, Ph.D. for personalized correction that no algorithm can replicate.
Three plans, one starting point: begin with free Chapter 1 to build speech-organ awareness before you practice a single sound. Move to the Basic Plan for self-study, or choose the Premium Plan if professional clarity is your goal. You can also schedule a free Premium session to experience 1-on-1 coaching before committing. Inpronunci is available on iOS and Android, serving learners from 50+ countries.
Useful sources
- The Problem with Pronunciation Feedback in AI Language Apps (Yapr) — Technical background on the STT bottleneck and acoustic-native analysis; use for understanding the core pipeline failure.
- Warning: 57% of AI Language Learning Apps Teach Unnatural Pronunciation Patterns (aitechmodel.com) — Empirical evidence on AI feedback quality and the 15-percentage-point accuracy gain from detailed phonetic systems.
- Assessing the Pedagogical Limitations of Duolingo in English Language Instruction (IJREHC) — Qualitative teacher case study; use for classroom limitation evidence and supplemental strategy data.
- Examining English Language Learning Apps from a Second Language Acquisition Perspective (ERIC) — Research review showing 82% of apps focus on language form over communicative competence; teacher resource.
- Challenges of Pronunciation Practices in the ESL Curriculum within the CLT Framework (ERIC) — Systematic review of curriculum-level pronunciation neglect; background for educators.
- A Review of Pronunciation Challenges Faced by ESL Learners from Different Varieties of Chinese — Peer-reviewed evidence on phonological transfer and fossilization; supports the advanced-learner consequences section.
- How to Improve Your English Pronunciation (British Council) — Authoritative learner guidance on recording, shadowing, and targeted drills; use for practice plan validation.
- InPronunci 2D Sound Video Mouth-Training Simulators Training Example (YouTube) — Speech-organ training in action; evidence asset for the case study section.
- Andrew’s Progress Video (YouTube) — Learner outcome evidence: before-and-after recording showing measurable progress through Inpronunci’s curriculum.
- Thiago’s Progress Video (YouTube) — Learner outcome evidence: before-and-after recording documenting stress and rhythm improvement.
- Tian’s Progress Video (YouTube) — Learner outcome evidence: before-and-after recording showing connected speech and vowel quality gains.
Questions & Answers
FAQ
01Why do ESL apps say my pronunciation is correct when it still sounds off?
Most apps score your speech by recognizing the words you said, not by analyzing how you produced them. If the speech-to-text engine identifies the right word, the app marks it correct, even when your vowel quality or stress pattern is far from a native model.
02What is the best way to practice pronunciation depth as an advanced learner?
Record yourself, compare to a native reference at the sentence level, and focus correction on stress, rhythm, and intonation, not just individual sounds. Short, frequent sessions with immediate feedback produce better motor retention than long, infrequent drills.
03What makes Inpronunci different from standard pronunciation apps?
Inpronunci’s AI Accent Coach analyzes your actual speech for pronunciation, intonation, rhythm, and connected speech, rather than converting audio to text first. Its Interactive Visual 2D Sound Simulators train tongue, lip, and jaw movement so you feel and produce the correct articulation, not just hear it.
04How long does it take to improve pronunciation with structured training?
With consistent daily practice and phoneme-level feedback, most advanced learners notice measurable suprasegmental improvement within 6–12 weeks. Segmental targets tend to stabilize in the first three weeks; stress and rhythm patterns follow in weeks four through six.
05Why can’t I seem to fix certain sounds even after months of practice?
Persistent errors often reflect phonological fossilization, where your native language’s sound system has overridden the target pattern. Fixing these requires explicit articulatory guidance and corrective feedback at the acoustic level, not more repetition of the same drill. A trained linguist or a system that analyzes raw audio, rather than text, is needed to break the pattern.
Recommended
Structured Pronunciation Training vs Apps Explained | Inpronunci
Discover the key differences between structured pronunciation training vs apps explained. Improve your American English with expert guidance!
Advanced ESL Pronunciation Techniques: Inpronunci’s Pro Guide
Master advanced ESL pronunciation techniques to enhance your confidence and clarity in American English. Transform your speech skills with expert training!
The Ultimate Pronounce App Guide 2026: Choosing Your AI Accent Coach
Find the best pronounce app to master your American accent. Our 2026 guide reviews AI accent coaches with visual feedback for executives seeking career growth.
Plans
What InPronunci costs
InPronunci Basic
$35 per month
Chapter 1 is free after signup.
InPronunci Premium
$200 per month
Includes a coach: